
Production Readiness
Your Code Is in GitHub. That Doesn't Mean You Can Recover Your App.
Your source code may be in GitHub while production still depends on data, files, secrets, authentication and platform state. A real recovery plan covers the whole operating system, not only the repository.
The problem
You connected your AI-built app to GitHub.
That is a good move.
It is also easy to overestimate what it gives you.
A Git repository can contain your React app, API code, SQL migrations and configuration files. But a production application is usually larger than its repository.
It may also depend on:
- live database data;
- object storage and uploaded files;
- environment variables and secrets;
- auth-provider configuration;
- payment webhooks;
- scheduled jobs;
- custom domains and DNS;
- deployment settings;
- production-only infrastructure state;
- monitoring, logs and alerting.
That distinction is showing up repeatedly in current founder discussions. In a convenience sample of 10 public Replit and Lovable threads reviewed for this article from 11 August to 10 September 2026, 9 explicitly discussed database/data access, deployment/environment state, migration/portability or production infrastructure control. This is not a prevalence estimate for AI-built apps. It is evidence of a recurring post-MVP question: “I have the code. Do I actually control production?”
GitHub solves one important part of the problem
Keeping your source in Git is good engineering.
It gives you history, diffs, branches, collaboration and a path to build somewhere else. Replit itself documents Git/GitHub as full version-control tooling.
But Replit's import documentation also makes the missing pieces clear. When importing Lovable or Bolt projects, code and database schema can come across while existing Supabase records and secrets do not. Other import paths similarly exclude environment values, custom domains, existing database data or platform-specific services.
That is the architectural lesson:
Source-code portability is not the same as production recoverability.
What your application actually looks like
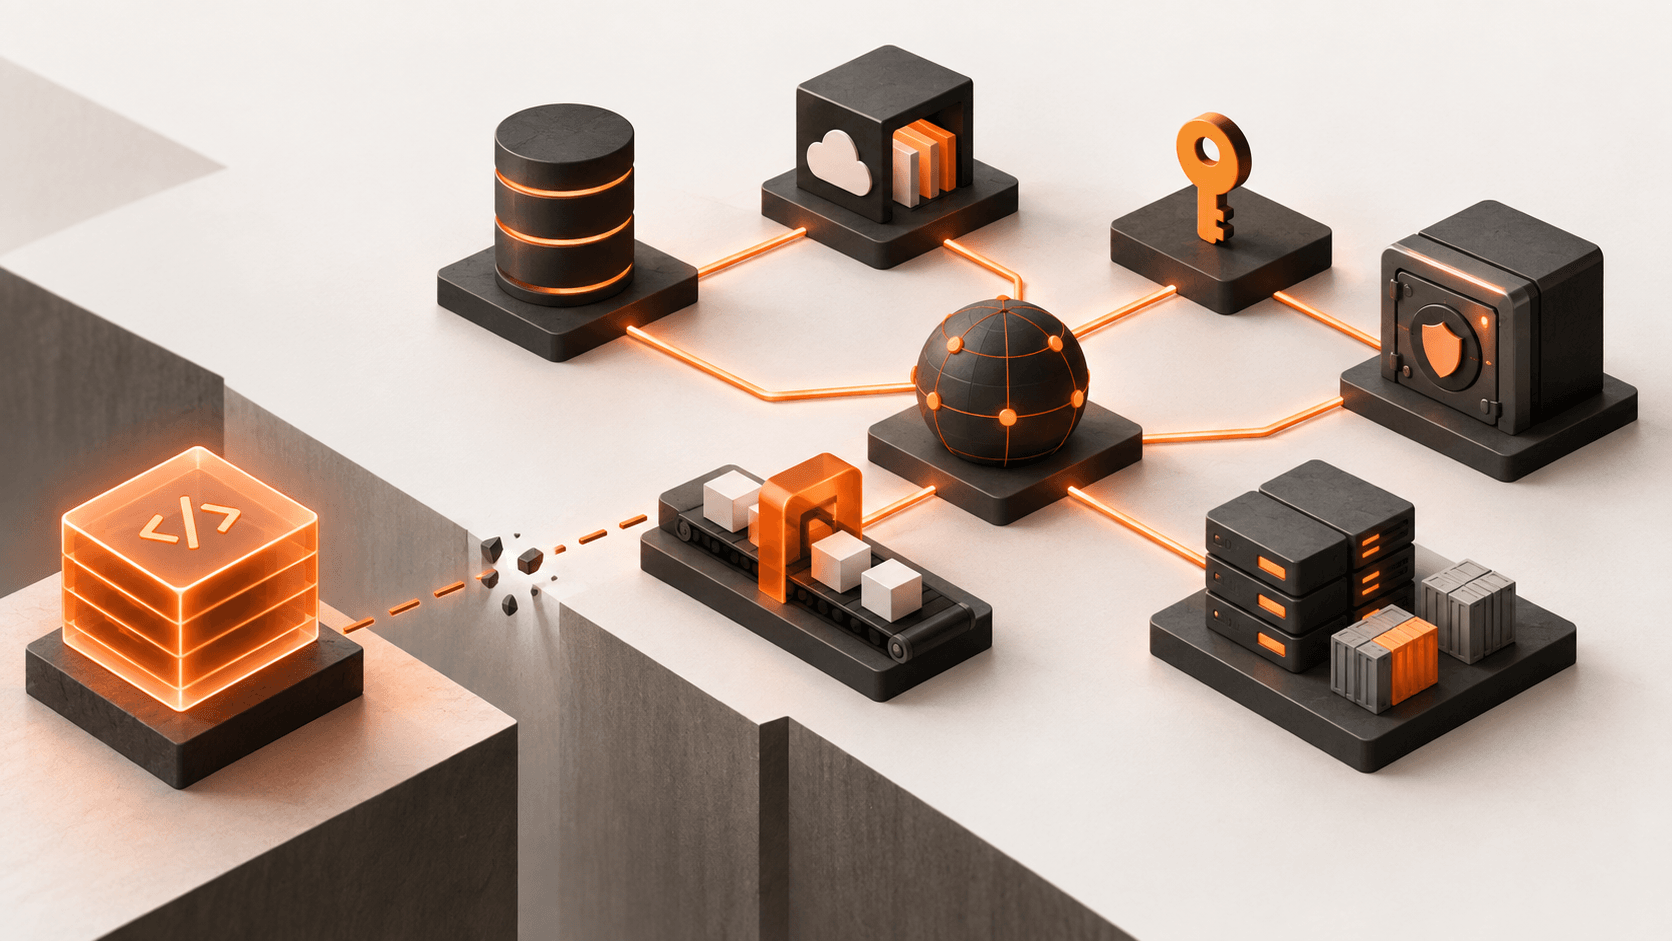
A modern AI-built SaaS might look more like this:
GitHub may give you the box labelled Application code.
Your customers depend on the whole diagram.
What is perfectly fine today
This is not an argument for abandoning managed platforms.
For an early product, keeping build, deploy, database and debugging close together can be a major advantage. The founder can ship faster and operate with less infrastructure knowledge.
You do not become more sophisticated by moving everything to AWS, Kubernetes or a VPS before you need to.
The question is not:
“Am I locked in?”
Every useful platform creates some dependency.
The better question is:
“If this dependency becomes a problem, do I understand what I would need to recover?”
What changes when the MVP becomes a business
The architecture may stay exactly the same while the consequence changes.
Yesterday:
- test accounts;
- fake data;
- one founder;
- no launch deadline.
Tomorrow:
- paying customers;
- uploaded files;
- production data;
- staff relying on the system;
- Stripe payments;
- customers expecting the service to be there.
At that point, “the platform usually handles it” is no longer the whole operating model.
Failure mode 1 — the repository is not what is running
One recent Replit founder explicitly raised uncertainty about whether GitHub matched what was actually running in production. A Lovable user separately described external edge functions and migrations syncing through GitHub without automatically being deployed, leaving production on older backend behaviour.
The practical control is simple:
You should be able to answer which commit is running in production.
If you cannot, recovery starts with ambiguity.
Failure mode 2 — you can rebuild the app but not its state
Imagine the builder disappeared for a day and you created a fresh deployment from GitHub.
What would the application contain?
Perhaps the UI and API.
Would it contain:
- customer records?
- uploaded files?
- auth users?
- webhook secrets?
- production environment variables?
- the correct DB schema version?
This is why backup and restore are two different capabilities.
A backup you have never restored is evidence that you copied something, not evidence that you can recover the business.
Failure mode 3 — development and production boundaries blur
Several fresh discussions involved development and production databases, secrets or deployment state becoming difficult to reason about.
This is dangerous even when nobody loses data.
A developer can believe they are testing against a safe environment while pointing at production. Or a production deployment can pick up the wrong secret, database URL or schema assumption.
You do not need complex infrastructure to reduce this risk. You need an explicit environment map.
- Asset: Database; Development: Dev DB; Production: Prod DB
- Asset: Secrets; Development: Dev keys; Production: Prod keys
- Asset: Domain; Development: Preview/staging; Production: Customer domain
- Asset: Payments; Development: Stripe test; Production: Stripe live
- Asset: Data; Development: Disposable; Production: Backed up + recoverable
Failure mode 4 — a platform incident becomes a business incident
A managed platform can have an outage. So can AWS. So can your own code.
The production-readiness question is not whether failure is possible.
It is whether you have enough independent visibility and control to make a decision when it happens.
Can you determine:
- Is the code unhealthy or the platform unhealthy?
- Is the database still intact?
- Is production pointing to the expected environment?
- Can you export the data?
- Can you deploy the last known-good commit elsewhere if necessary?
- Who controls the domain?
If every answer requires the same broken control plane or support ticket, one operational dependency has accumulated too much responsibility.
The recovery test I would run before a rewrite
Do not migrate everything.
Run a tabletop recovery exercise.
Assume your builder is unavailable for 24 hours.
Can you identify, without changing production:
- the exact production commit;
- the production database and schema version;
- where customer files live;
- which secrets the runtime requires;
- who controls auth configuration;
- who controls the domain and DNS;
- how to export or restore production data;
- how you would create a fresh deployment from source.
Then test the parts that are safe to test in staging.
You are not trying to prove that you can leave the platform tomorrow.
You are trying to remove unknowns.
A useful way to think about RTO and RPO
Two reliability terms help here without turning this into enterprise theatre.
RTO — Recovery Time Objective: how long could the product reasonably be unavailable before it becomes a serious business problem?
RPO — Recovery Point Objective: how much recent data could you reasonably lose?
An early beta may tolerate a long RTO and manual recovery.
A product processing orders or running a customer's daily operation probably cannot.
Your architecture should match the consequence.
Signals that mean you should do this now
A recovery/ownership review becomes valuable when any of these are true:
- real customer or personal data is stored;
- people are paying;
- uploaded files would be difficult to recreate;
- the app has multiple production integrations;
- staff or customers rely on it operationally;
- a platform change or outage has already surprised you;
- nobody can confidently explain how production differs from development;
- moving the app would currently require discovering the architecture while under pressure.
What not to over-engineer
You probably do not need:
- multi-cloud;
- Kubernetes;
- active-active databases;
- a custom deployment platform;
- a full SRE team;
- to leave Lovable, Replit or Supabase just because the product has traction.
For many early products, production hardening may be as small as:
- GitHub as an external source repository;
- a documented production asset map;
- tested DB backup/export;
- clear dev/prod secrets;
- domain ownership you understand;
- a smoke test after every publish;
- a short recovery runbook.
That is enough to turn “I hope the platform has it” into “I know how the system is put together.”
Production readiness is not zero vendor dependency
A production-ready system is not one with zero vendor dependency.
That is unrealistic.
A better standard is:
Use managed platforms aggressively where they buy speed. Keep enough ownership to understand, verify and recover the parts your business depends on.
GitHub is part of that.
It is not the whole recovery plan.
The Production Gap often appears precisely here: the software is functional, but operational ownership has not caught up with how important the product has become.
Sources
- Replit — production platform reliability thread, 10 Sep 2026
- Replit — production DB / DATABASE_URL thread, 7 Sep 2026
- Replit — safe production DB migration thread, 2 Sep 2026
- Replit — dev DB/live DB environment confusion, 1 Sep 2026
- Replit — production confidence and portability thread, 31 Aug 2026
- Lovable — “MVP is up and running, what’s next?”, 29 Aug 2026
- Replit — publishing and production data thread, 24 Aug 2026
- Replit — moving a production app off-platform, 17 Aug 2026
- Lovable — production backend/auth reliability thread, 12 Aug 2026
- Lovable — self-host migration thread, 11 Aug 2026
- Replit import documentation
- Replit version-control documentation
What's next for you?
If your app is already live, do not start with a rewrite. Start by mapping what the product depends on, which parts you can recover, and which assumptions are still unknown. That gives you a practical next step without adding infrastructure you do not yet need.